Catching Schema Drift Before It Breaks Production
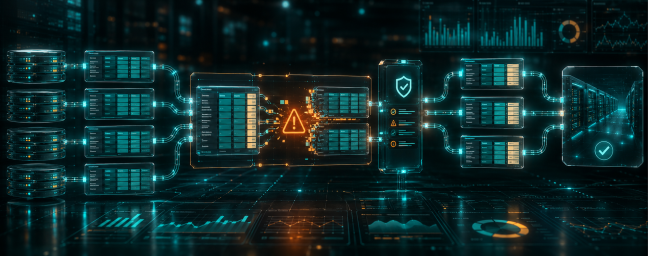
Schema drift is not an exception. It is the steady state of enterprise data. Source systems get refactored, third-party APIs add and remove fields between versions, and upstream teams rarely think to notify every downstream consumer before shipping a change. The goal is not to prevent change but to detect it within one run and route it safely.
Most schema-related outages we investigate share a common shape: a column quietly changed type, a nested field was renamed, or a previously required field started arriving as null. None of these are unusual events in a large organization. What makes them costly is that they are discovered downstream, often by a business user noticing a dashboard looks wrong, rather than by the pipeline itself.
Every ingestion job should know the shape it expects and what to do when reality disagrees.
Classify before you react
Snapshot the inferred schema on every run, diff it, and classify changes as additive, narrowing, or breaking. Additive changes flow through; breaking ones quarantine the batch and open an alert with the exact field-level delta. This classification step is what separates a system that cries wolf on every harmless addition from one engineers actually trust.
An additive change, such as a new optional field appearing in a payload, should never block a pipeline. A narrowing change, such as a field that used to allow nulls suddenly requiring a value, deserves a warning but can often still proceed. A breaking change, such as a type change on a field used in a join key, should stop the batch immediately and surface a precise diff so the on-call engineer does not have to reverse-engineer what happened from raw logs.
Absorbing drift without losing history
Quarantining a batch is only half the solution. The other half is making sure the quarantine does not silently create a gap in downstream history. We recommend holding the raw quarantined data untouched in a staging area, publishing an alert with enough context for a human to make a call within minutes, and automatically reprocessing once the schema mapping is updated, so the eventual fix backfills cleanly instead of leaving a permanent hole in the timeline.