AI Data Engineering Platform

Turning Enterprise Data Into Intelligence

DataMeadaw helps enterprise teams bring data from different sources together, transform it, improve its quality, and prepare reliable data for analytics and AI.

Trusted by enterprise data teams

NORTHWINDALTAMESAVERIDIANKESTRELSOLARISBLUEFORD

Pipeline Operations

Transformation Throughput

Live
DataMeadaw pipeline overview
MonTueWedThuFriSatSun

128

Active pipelines

99.7%

Quality score

1.2M

Records/min

2.4B+

Records Processed

99.7%

Data Quality Score

60%

Faster Pipelines

500+

Enterprise Datasets

The Platform

Powering Your Enterprise Data Journey

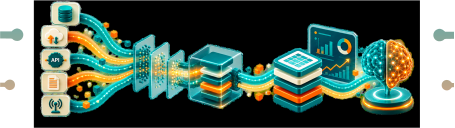
From data that comes from big companies to data that can be trusted and used with artificial intelligence. DataMeadaw helps you handle each step in one single platform that is all connected.

Step 1

Enterprise Data Sources

Step 2

Data Ingestion

Step 3

Intelligent Transformation

Step 4

Quality & Enrichment

Step 5

AI-Ready Data

Platform Capabilities

One Workspace for Modern Data Teams

Data Ingestion Engine

Connect your enterprise sources once and move data into a governed landing layer with minimal custom code.

  • Database connectivity (Postgres, Oracle, SQL Server, Snowflake)
  • API ingestion with pagination, retries and schema discovery
  • File processing for CSV, Parquet, JSON and Excel at scale
  • Cloud ingestion from S3, GCS, Azure Blob and lakehouses
  • Streaming integration for Kafka, Kinesis and IoT event feeds
Data Transformation Engine

Declarative, versioned transformations that turn raw enterprise records into analytics-grade models.

  • Normalization of types, units, encodings and time zones
  • Schema transformation and mapping with drift detection
  • Cleaning rules for nulls, outliers and malformed values
  • Enrichment joins against reference and third-party data
  • Pipeline automation with dependencies and scheduling

Data Quality Intelligence

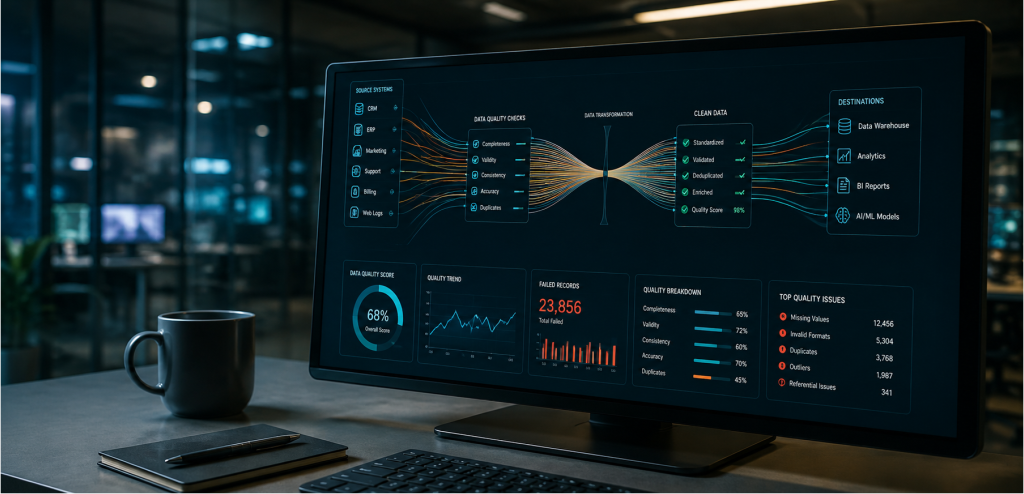
Continuous, automated quality scoring so teams trust every dataset before it reaches a model or dashboard.

  • Validation rules and contract enforcement per dataset
  • Duplicate and near-duplicate detection across sources
  • Missing data identification with impact scoring
  • Consistency analysis between systems of record
  • Quality monitoring with alerting and historical trends

AI Data Preparation

Turn governed datasets into training-ready and retrieval-ready assets without hand-rolled notebooks.

  • Dataset preparation with splits, sampling and labelling hooks
  • Feature engineering library with reusable definitions
  • Semantic enrichment and embedding-ready text pipelines
  • Storage and format optimization for GPU workloads
  • AI-ready pipelines wired to training and inference targets

Data Operations Dashboard

A single operational view of every pipeline, volume, failure and readiness signal across the estate.

  • Active pipelines and run history at a glance
  • Processing volume and throughput trends
  • Transformation status per stage and dataset
  • Performance metrics with bottleneck attribution
  • Quality metrics, failure triage and dataset readiness

Pricing

Plans for Every Stage of Your Data Journey

Start with the essentials, give your team more powerful data tools, or scale DataMeadaw across your enterprise.

Starter

For individual data engineers & small teams

$0to start
  • Usage-based pricing as you grow
  • Core data ingestion (up to 3 sources)
  • Basic transformation tools
  • Limited pipeline automation
  • Community support
Start Free
Most Popular

Team

For growing data teams

$49/seat/mo
  • Unlimited data sources
  • Full transformation engine
  • Data quality intelligence
  • AI data preparation tools
  • Pipeline monitoring dashboard
  • Priority email support
Get Started with DataMeadaw

Enterprise

For enterprise data infrastructure

Custom
  • Dedicated deployment
  • Enterprise licensing
  • Custom SLAs
  • Full API access
  • Dedicated data engineering support
  • Security & compliance review
Contact Sales

Need a custom data volume plan? Reach out to our team.

Testimonials

Perspectives from Modern Data Teams

See how teams use DataMeadaw to simplify data engineering and prepare reliable data for AI.

DataMeadaw helps our team bring data from different sources together and manage transformation and quality in one place. It has made our daily data work more organized and easier to manage.
60% faster pipelines
Daniel OkaforDaniel OkaforHead of Data Engineering, Northwind Payments
We use DataMeadaw to identify missing and duplicate data and improve the quality of our datasets. This gives our team more confidence when using data for analytics and AI projects.
94% fewer duplicates
Marisol VegaMarisol VegaVP of Analytics, Altamesa Retail Group
DataMeadaw helps us organize our data workflows and prepare reliable data for analytics and AI. Having these capabilities together makes our data operations easier to manage.
9 weeks → 11 days
Arjun MehtaArjun MehtaChief Data Officer, Veridian Health AI
Rated 4.8/5 by data engineering teams· 240+ verified reviews

FAQ

Everything You Need to Know

Founded July 2023 · Enterprise Data Infrastructure

Why We Built DataMeadaw

We spent a decade inside enterprise data teams watching the same pattern repeat: critical information scattered across databases, APIs, cloud platforms and IoT systems, with no single place to make it usable. Every analytics or AI initiative started by rebuilding the same ingestion and cleaning work from scratch.

DataMeadaw was created in July 2023 to reduce that duplication. We built one environment where data ingestion, transformation, quality intelligence and AI preparation work together with shared lineage, contracts, and monitoring. Our mission is to make trusted, high-quality data faster and easier to prepare for analytics and AI, never the bottleneck.

Today DataMeadaw operates as DataMeadaw Analytics LLC in the United States, serving enterprise data teams globally.

SpeedShip governed datasets in days, not quarters.
AccuracyValidation at every stage, scored continuously.
ReliabilityPipelines that survive drift and scale.
Data IntelligenceContext-aware enrichment and preparation.
Built by data engineers, for data engineers10+ years combined enterprise data experience
Aadhiran Yaalvendhan

Aadhiran Yaalvendhan

Founder, DataMeadaw

Founded July 2023

Mission in numbers

Enterprise datasets governed500+
Average pipeline build-time saved60%
Mean data quality score99.7%
Records processed to date2.4B+

From the Blog

Data Engineering Insights

Keep yourself updated with ideas about data engineering insights, intelligence and smarter ways to manage data.

Visit the Blog

Contact

Let's Talk About Your Data

Whether you're exploring the platform or ready for enterprise deployment, our team is here to help.

DataMeadaw Analytics LLC

  • 601 South Figueroa Street, Suite 4050, Los Angeles, CA 90017, USA
  • +1 213 555 3109

Prefer email?

help@datameadaw.com

For enterprise & custom deployments

Dedicated deployment, licensing and SLA discussions go straight to our solutions architects.

Contact Sales →
Developer Docs

Build on the DataMeadaw API

  • · Data ingestion APIs
  • · Transformation guides
  • · Pipeline integration & webhooks
  • · Data quality resources
  • · AI data prep guides
  • · Python & Node SDKs

Everything you can do in the dashboard is available through the API — from registering sources to reading live quality scores.

Read the Docs